


The Importance of Independent Validation Sets in Machine Learning
In machine learning, the use of independent validation sets is crucial for evaluating model performance and avoiding one of the most common pitfalls: overfitting. Overfitting occurs when a model is trained to perform exceptionally well on the training data but fails to generalize to new, unseen data. This typically happens when the model is excessively complex for the given task or when it memorizes the noise and peculiarities of the training dataset instead of learning the underlying patterns.
An independent validation set helps to detect overfitting by providing a dataset that is separate from the training set, allowing for an unbiased evaluation of the model’s performance. Moreover, selecting the model that performs best on an independent validation set ensures that we are choosing a model that is most likely to generalize well to new data, rather than simply performing well on the training data.
To split data into a training and a validation set, scikit-learn provides the function train_test_split, which randomly partitions the data into a training set and a held-out set (which scikit-learn calls the test set). By default, train_test_split holds out 25% of the data, but this can be adjusted using the test_size parameter.
Example of Overfitting
Below, we create a small dataset of 10 data points, and compare three regression models of increasing complexity: a linear model, a quadratic model and an eighth-degree polynomial model.
import numpy as np
import matplotlib.pyplot as plt
from sklearn.preprocessing import PolynomialFeatures
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_squared_error
from sklearn.model_selection import train_test_split

# Generating synthetic data
np.random.seed(42)
x = np.linspace(-3, 3, 10).reshape(-1, 1)
y = 0.5 * x**2 + np.random.normal(0, 0.5, x.shape)

# Splitting the data into training and validation sets
x_train, x_val, y_train, y_val = train_test_split(x, y, test_size=0.3, random_state=42)

# Creating a linear, a quadratic and an eighth-degree polynomial regression model
linear_model = LinearRegression()
quad_model = LinearRegression()
poly_model = LinearRegression()
quadratic_features = PolynomialFeatures(degree=2)
polynomial_features = PolynomialFeatures(degree=8)

# Fitting the models
linear_model.fit(x_train, y_train)
x_quad = quadratic_features.fit_transform(x_train)
quad_model.fit(x_quad, y_train)
x_poly = polynomial_features.fit_transform(x_train)
poly_model.fit(x_poly, y_train)

# Predicting using the fitted models
y_linear_train_pred = linear_model.predict(x_train)
y_linear_val_pred = linear_model.predict(x_val)
y_quad_train_pred = quad_model.predict(quadratic_features.transform(x_train))
y_quad_val_pred = quad_model.predict(quadratic_features.transform(x_val))
y_poly_train_pred = poly_model.predict(polynomial_features.transform(x_train))
y_poly_val_pred = poly_model.predict(polynomial_features.transform(x_val))

# Calculating and printing train and validation errors for each model
linear_train_error = mean_squared_error(y_train, y_linear_train_pred)
linear_val_error = mean_squared_error(y_val, y_linear_val_pred)
quad_train_error = mean_squared_error(y_train, y_quad_train_pred)
quad_val_error = mean_squared_error(y_val, y_quad_val_pred)
poly_train_error = mean_squared_error(y_train, y_poly_train_pred)
poly_val_error = mean_squared_error(y_val, y_poly_val_pred)

print(f"Linear Model - Train Error: {linear_train_error:.2f}, Validation Error: {linear_val_error:.2f}")
print(f"Quadratic Model - Train Error: {quad_train_error:.2f}, Validation Error: {quad_val_error:.2f}")
print(f"High-Degree Model - Train Error: {poly_train_error:.2f}, Validation Error: {poly_val_error:.2f}")

# Plotting the data, and the models' predictions on a grid of x values
x_grid = np.linspace(-3, 3, 100).reshape(-1, 1)
y_linear_pred = linear_model.predict(x_grid)
y_quad_pred = quad_model.predict(quadratic_features.transform(x_grid))
y_poly_pred = poly_model.predict(polynomial_features.transform(x_grid))

plt.scatter(x_train, y_train, color='black', label='Training Data')
plt.scatter(x_val, y_val, color='gray', label='Validation Data')
plt.plot(x_grid, y_linear_pred, label='Linear Model (Underfitting)', color='blue')
plt.plot(x_grid, y_quad_pred, label='Quadratic Model', color='green')
plt.plot(x_grid, y_poly_pred, label='High-Degree Model (Overfitting)', color='red')
plt.legend()
plt.xlabel("x")
plt.ylabel("y")
plt.show()
Linear Model - Train Error: 2.90, Validation Error: 1.85
Quadratic Model - Train Error: 0.08, Validation Error: 0.28
High-Degree Model - Train Error: 0.00, Validation Error: 67.64
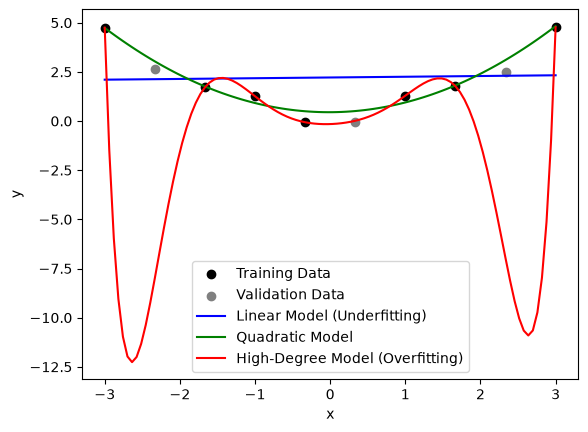
The linear model misses the curvature of the data, and has a large error on both the training data (2.90) and the validation data (1.85); it is underfitting. The eighth-degree model has nine parameters but only seven training points, so it passes exactly through every training point (training error 0.00), but swings wildly between them and has a validation error of 67.64; it is overfitting. The quadratic model, which matches how the data were generated, has a low error on both sets.
Cross Validation to the Rescue
A problem with a separate validation set is that we have to reserve precious data for either training or validation, while we would like to use as much data as possible for both. Cross validation solves this by partitioning the data into multiple subsets, or folds, so that every data point is used both for training and for validation, and thereby estimates how well a model generalizes to new samples while still using all available data.
In k-fold cross validation, the dataset is split into k equally sized folds. The model is trained k times, each time using a different fold as the validation set and the remaining folds for training. The average of the validation metrics across all folds gives a more robust estimate of the model’s performance compared to using a single validation set.
Illustration of Three-Fold Cross Validation
Imagine we have a dataset with six data points, represented as A, B, C, D, E, F. In three-fold cross validation, we can split this dataset into three subsets, each containing two data points. For example:
Fold 1: Training on
[C, D, E, F], Validation on[A, B]Fold 2: Training on
[A, B, E, F], Validation on[C, D]Fold 3: Training on
[A, B, C, D], Validation on[E, F]
Here is a code example illustrating three-fold cross validation with six data points. Note that the code shuffles the data before splitting it, so its folds differ from the ones listed above:
from sklearn.model_selection import KFold

# Example dataset with six data points
x_example = np.array([[1], [2], [3], [4], [5], [6]])
y_example = np.array([1, 4, 9, 16, 25, 36])

# Setting up three-fold cross validation
kf_example = KFold(n_splits=3, shuffle=True, random_state=42)

for fold, (train_index, val_index) in enumerate(kf_example.split(x_example)):
    print(f"Fold {fold + 1}: Training on {x_example[train_index].flatten()}, Validation on {x_example[val_index].flatten()}")
Fold 1: Training on [3 4 5 6], Validation on [1 2]
Fold 2: Training on [1 2 4 5], Validation on [3 6]
Fold 3: Training on [1 2 3 6], Validation on [4 5]
Cross Validation to detect overfitting
We now use three-fold cross validation with scikit-learn’s KFold to compare the second-degree and the eighth-degree polynomial models on the ten data points from above:
from sklearn.model_selection import KFold
from sklearn.pipeline import make_pipeline

# Creating a pipeline for polynomial regression with degree 2 and 8
pipeline_2 = make_pipeline(PolynomialFeatures(degree=2), LinearRegression())
pipeline_8 = make_pipeline(PolynomialFeatures(degree=8), LinearRegression())

# Setting up three-fold cross validation
kf = KFold(n_splits=3, shuffle=True, random_state=42)
scores_2, scores_8 = [], []

for train_index, val_index in kf.split(x):
    x_train, x_val = x[train_index], x[val_index]
    y_train, y_val = y[train_index], y[val_index]
    # Fit and validate second degree polynomial
    pipeline_2.fit(x_train, y_train)
    y_pred = pipeline_2.predict(x_val)
    mse = mean_squared_error(y_val, y_pred)
    scores_2.append(mse)
    # Fit and validate eighth degree polynomial
    pipeline_8.fit(x_train, y_train)
    y_pred = pipeline_8.predict(x_val)
    mse = mean_squared_error(y_val, y_pred)
    scores_8.append(mse)

# Calculating and printing the mean score
print(f"Mean cross-validated MSE, for 2nd degree: {np.mean(scores_2):.2f} and for 8th degree: {np.mean(scores_8):.2f}")
Mean cross-validated MSE, for 2nd degree: 0.23 and for 8th degree: 11003.98
The mean squared error (MSE) is calculated on the validation fold of each round, and averaged over the three folds. The second-degree model has a cross-validated MSE of 0.23, while the eighth-degree model, which has more parameters than there are training points in each round, has an MSE of about 11,000. Cross validation thus exposes the overfitting without setting aside a separate validation set.
Hyperparameter Selection
Hyperparameters are parameters of the machine learning model that are not learned from the training data but are instead set before training begins. Examples include the degree of a polynomial model, the strength of the regularization in ridge and LASSO regression, and the learning rate in gradient descent. Proper selection of hyperparameters is crucial to maximize a model’s performance. A common method for selecting them is grid search with cross validation, and nested cross validation lets us estimate how well the resulting model, including its hyperparameter selection, performs on new data.
Grid Search for Hyperparameter Tuning
Grid search is a brute-force method for finding the optimal hyperparameter values for a given model. It involves specifying a grid of hyperparameter values and then training and evaluating the model for each combination of parameters. The combination that yields the best performance on the validation set is selected as the final set of hyperparameters.
Let’s consider an example where we are training a LASSO regression model, and we want to determine the optimal value for the hyperparameter, . LASSO regression is a linear model that includes L1 regularization, which helps to prevent overfitting by adding a penalty to the magnitude of the parameters, effectively setting some of them to zero. Here plays the same role as the regularization parameter in the regularization chapter; scikit-learn calls it . With grid search, we define a range of possible values for and iterate over each value, training and evaluating the model at each step.
The following code uses scikit-learn’s GridSearchCV to perform a grid search over the regularization parameter of a LASSO regression model, on 100 data points generated from a second-order polynomial with Gaussian noise:
import numpy as np
from sklearn.model_selection import GridSearchCV, KFold
from sklearn.linear_model import Lasso
from sklearn.preprocessing import PolynomialFeatures
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

# Generating synthetic data from a second order polynomial with Gaussian noise
np.random.seed(42)
x = np.linspace(-3, 3, 100).reshape(-1, 1)
y = 0.5 * x**2 + np.random.normal(0, 0.5, x.shape)

# Creating a pipeline for polynomial regression with Lasso regularization
model = make_pipeline(PolynomialFeatures(degree=5), StandardScaler(), Lasso(max_iter=10000))

# Defining the parameter grid
param_grid = {'lasso__alpha': [0.01, 0.1, 1, 10, 100]}

# Setting up GridSearchCV with three-fold cross validation on shuffled data
cv = KFold(n_splits=3, shuffle=True, random_state=42)
grid_search = GridSearchCV(model, param_grid, cv=cv, scoring='neg_mean_squared_error')

# Performing the grid search
grid_search.fit(x, y)

# Printing the best parameters
print(f"Best hyperparameters: {grid_search.best_params_}")

# Printing the parameters for each value of alpha
for i, estimator in enumerate(grid_search.cv_results_['params']):
    alpha = estimator['lasso__alpha']
    model.set_params(**estimator)
    model.fit(x, y)
    lasso = model.named_steps['lasso']
    print(f"Alpha: {alpha}, parameters for model {i + 1}: {lasso.coef_}")
Best hyperparameters: {'lasso__alpha': 0.01}
Alpha: 0.01, parameters for model 1: [ 0. 0.10553842 1.23103587 -0. 0.1622308 -0.11625395]
Alpha: 0.1, parameters for model 2: [ 0. 0. 1.18498276 -0. 0.11636712 -0. ]
Alpha: 1, parameters for model 3: [0. 0. 0.39640516 0. 0. 0. ]
Alpha: 10, parameters for model 4: [0. 0. 0. 0. 0. 0.]
Alpha: 100, parameters for model 5: [0. 0. 0. 0. 0. 0.]
GridSearchCV runs a three-fold cross validation for each value of in the grid, and selects the value with the lowest cross-validated MSE, here . Note that we shuffle the data before splitting it into folds. As our values are sorted, each fold would otherwise cover a contiguous third of the range, and the models would be judged on how well they extrapolate rather than on new points from the same range.
Nested Cross Validation
The cross-validated performance of the best hyperparameter value in a grid search is optimistic, as that value was selected precisely because it performed best on these validation folds. Using the same validation data both to tune the hyperparameters and to evaluate the model is thus a form of overfitting. To address this issue, nested cross validation is used.
In nested cross validation, there are two loops:
The outer loop is used to split the data into training and testing sets, ensuring that the test set remains completely independent.
The inner loop is used to perform grid search on the training set, determining the best hyperparameters.
The following code performs nested cross validation with scikit-learn:
from sklearn.model_selection import cross_val_score
from sklearn.model_selection import KFold

# Setting up the inner and outer cross validation loops
inner_cv = KFold(n_splits=3, shuffle=True, random_state=42)
outer_cv = KFold(n_splits=5, shuffle=True, random_state=42)

# Using GridSearchCV within cross_val_score for nested cross validation
grid_search = GridSearchCV(model, param_grid, cv=inner_cv, scoring='neg_mean_squared_error')
nested_scores = cross_val_score(grid_search, x, y, cv=outer_cv)

print(f"Nested cross-validated MSE: {-nested_scores.mean():.2f} (+/- {nested_scores.std():.2f})")
Nested cross-validated MSE: 0.21 (+/- 0.10)
Here the outer loop (outer_cv) splits the dataset into five folds, and for each of them the inner loop (inner_cv) runs a three-fold grid search on the remaining four folds. As the outer validation folds are never used to select , the average MSE over them, 0.21, is a nearly unbiased estimate of the performance of the whole procedure, including the hyperparameter selection. Since the error is calculated on five separate validation folds, cross validation also tells us how much the performance varies, here with a standard deviation of 0.10 over the folds.
What you should know after reading this chapter
You should be able to:
Explain what overfitting and underfitting are, and identify them from the training and validation errors of models of different complexity, such as a linear, a quadratic and an eighth-degree polynomial model.
Explain why a model’s performance must be estimated on data that were not used to train it.
Describe k-fold cross validation, and write out by hand how a small dataset, such as six data points in three folds, is split so that every point is used for validation exactly once.
Explain the advantages of cross validation over a single validation set: all data are used for both training and validation, and the spread over the folds gives an estimate of the variance of the performance.
Define a hyperparameter, contrast it with the parameters learned from the training data, and describe how grid search with cross validation selects a hyperparameter such as the LASSO regularization parameter .
Explain why the validation performance of the best setting in a grid search is optimistic, and describe how nested cross validation, with an inner loop for tuning and an outer loop for evaluation, avoids this.